Bug Fixing & Stability Engineering
Find, reproduce, and fix issues across React/Next.js, Node/Express, Python APIs, Android, and Shopify/WordPress. Add tests, logging, and monitoring to prevent regressions and keep releases stable.
- First findings
- Within the first week
- Typical engagement
- 2 to 8 weeks
- Model
- Fixed sprint or monthly retainer
From fragile to dependable, one root cause at a time.
When software crashes, slows down or breaks every time someone ships a change, the cost is more than the bug itself. It is lost customers, a support queue that never empties and a team afraid to touch the code. We fix the immediate problems and the reasons they keep happening.
We begin by making the system observable: error tracking, logs and performance monitoring, so decisions are based on what is actually failing and how often. From there we fix issues in order of business impact and add tests around every fix so the same problem cannot quietly return.
The work ends with a codebase your team can change with confidence: a regression suite, a deploy pipeline that catches mistakes before customers do, and clear notes on the risks that remain.
- Products with frequent crashes, errors or slow pages
- Teams that inherited a codebase from a previous agency or developer
- Companies about to scale who need confidence the system will hold
- Founders who need a stable product before raising or selling
Everything it takes, in one engagement.
Every part of bug fixing & stability engineering handled by one senior team, so nothing falls between suppliers and you always know who owns the result.
Codebase and risk audit
A structured review of architecture, dependencies, security and test coverage, with findings ranked by business risk.
Observability setup
Error tracking, structured logging, uptime checks and performance monitoring, so problems are visible before users report them.
Root-cause fixing
We trace each failure to its source and fix that, rather than adding another workaround on top.
Performance tuning
Slow queries, heavy pages, memory leaks and inefficient code paths found with profiling and fixed with measurements.
Automated testing
Unit, integration and end-to-end tests around critical journeys, so every future change is checked automatically.
Safer releases
CI pipelines, staging environments and rollback paths that make deploying a routine event instead of a risk.
- Audit report with prioritised findings
- Error tracking and monitoring in place
- Fixed critical and high-priority issues
- Regression test suite for key journeys
- CI pipeline with automated checks
- Stability roadmap for the remaining risks
Tools we trust in production.
Proven, well-supported technology chosen for your product, not for our habits. Everything here is something we run in production.
- Sentry
 Datadog
 Grafana
 Prometheus
 Playwright
- Cypress
 Jest
 Vitest
 TypeScript
 Node.js
 Python
 GitHub Actions
What this does for your business.
Fewer fires, calmer teams
Recurring incidents are solved at the root, so your people spend their time building instead of firefighting.
Releases without fear
Automated tests and safer pipelines mean shipping a change no longer risks breaking something else.
Users who stay
A faster, more reliable product reduces support tickets, refunds and the quiet churn that bugs cause.
From first call to shipped.
A planned, transparent arc with something you can see every week, so you always know exactly where the work stands.
Triage
Days 1 to 3We get access, reproduce the urgent issues and stop any active damage first.
Instrument and audit
Week 1Monitoring goes in and the codebase is reviewed, giving a clear, ranked picture of what is wrong.
Fix by impact
Weeks 2 to 6Issues are resolved in order of business impact, each with a test that proves it is fixed.
Guard the gains
Final weeksRegression tests, CI checks and release practices that keep the system stable as work continues.
Hand over or stay on
OngoingA written summary of what changed and what remains, with optional ongoing maintenance.
 Engineering
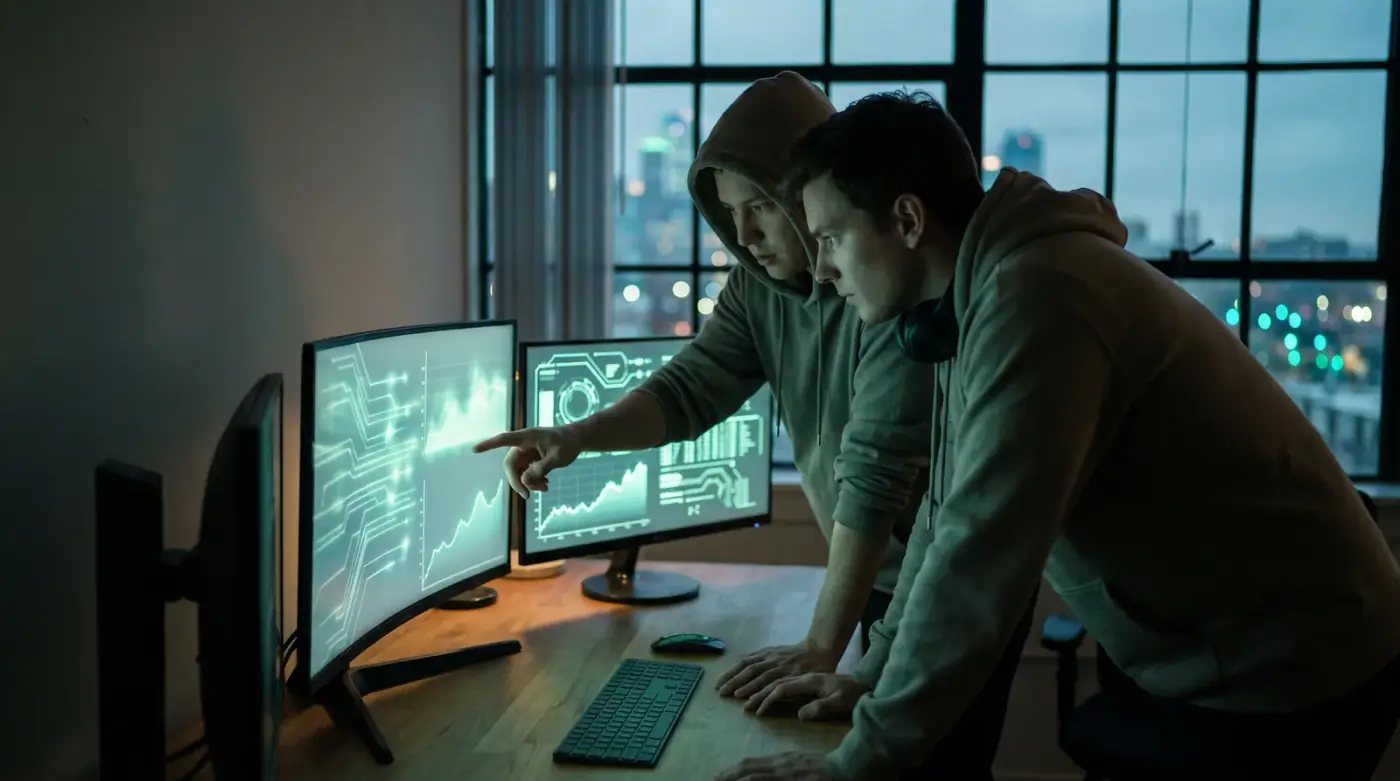
A software company inherits a product that crashes weekly. We add error tracking and tests, fix the root causes in order of impact and hand back a stable platform with a regression suite guarding every future release.
Talk to us about a project like thisQuestions we hear a lot.
Something else on your mind? Ask Luma in the corner, or reach the team directly.
Ask a questionYes, that is most of this work. We start with an audit so we understand the codebase before changing it, and we document what we learn as we go.
Explore related services.
Need bug fixing & stability engineering done right?
Tell us about your project, we'll come back with a concrete plan and timeline.