MLOps & Model Deployment
Operationalize PyTorch models with containerized monitoring. Automate training and rollouts using Docker and GitHub Actions.
- Typical timeline
- 4 to 10 weeks
- Deploys to
- AWS, Google Cloud, Azure, on-premise
- Engagement
- Project or embedded with your team
From notebook to a model you can run, trust and improve.
Many machine learning models never leave the notebook they were trained in. We build the infrastructure that takes them into production: packaged, served behind a reliable API, monitored and retrained as the world changes.
That means versioned data and models, automated training and evaluation pipelines, deployment with safe rollouts and dashboards that show when accuracy starts to drift. Your data scientists keep doing science; the pipeline handles the rest.
We work with your existing cloud and tools wherever possible, and design for cost as much as performance, including GPU usage, batching and model optimisation.
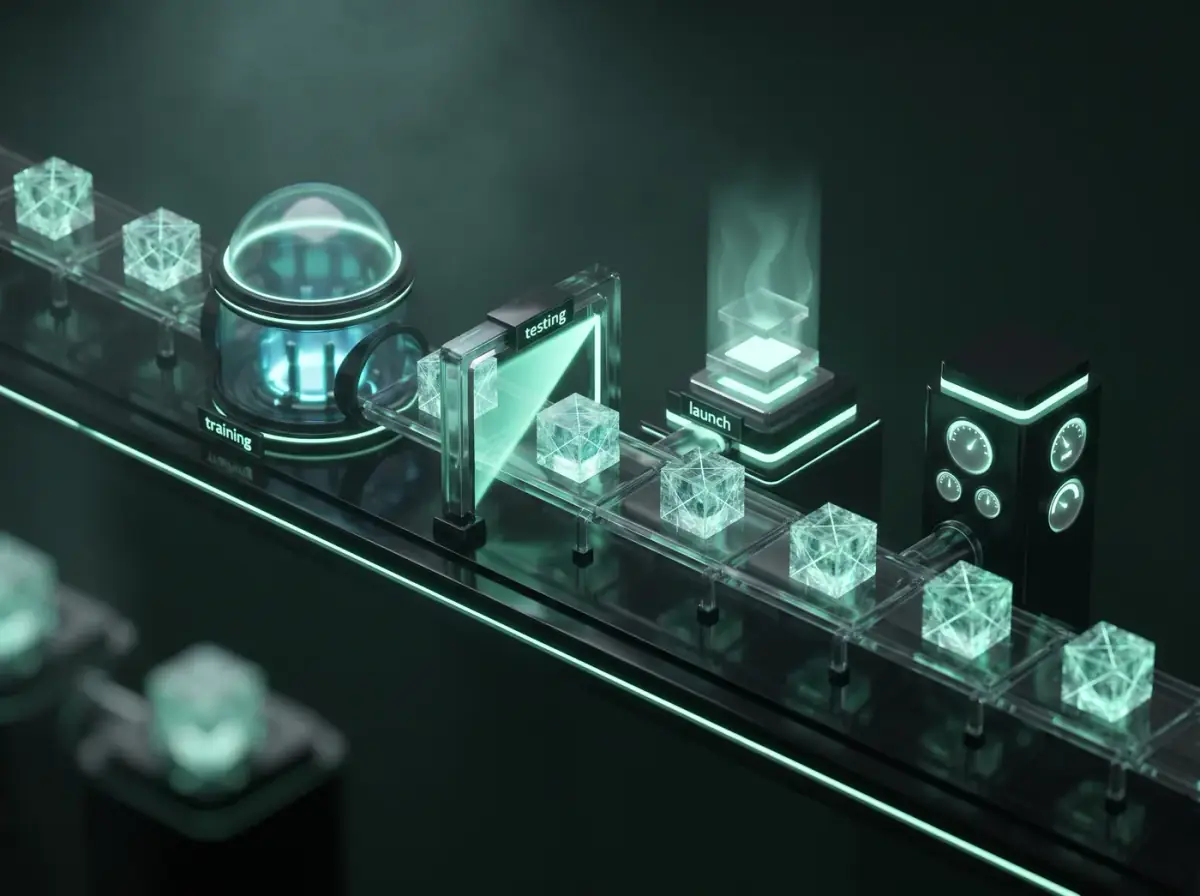
- Data science teams with models stuck in notebooks
- Companies running models in production without monitoring
- Products that need low-latency inference at scale
- Teams retraining models by hand and wanting it automated
Everything it takes, in one engagement.
Every part of mlops & model deployment handled by one senior team, so nothing falls between suppliers and you always know who owns the result.
Model packaging and serving
Models containerised and served through fast, versioned APIs with autoscaling for real traffic.
Training pipelines
Reproducible pipelines for data preparation, training and evaluation, triggered on schedule or by new data.
Experiment and model tracking
Every run, dataset and model version recorded, so results can be compared and reproduced.
CI/CD for machine learning
Automated tests and quality gates that decide whether a new model is good enough to replace the current one.
Monitoring and drift detection
Dashboards and alerts for latency, errors, data drift and accuracy, so problems are caught early.
Inference optimisation
Quantisation, ONNX export, batching and GPU tuning that cut latency and infrastructure cost.
- Production model serving API
- Automated training and evaluation pipeline
- Model registry and experiment tracking
- Monitoring dashboards and drift alerts
- Deployment pipeline with safe rollouts
- Runbooks and team handover
Tools we trust in production.
Proven, well-supported technology chosen for your product, not for our habits. Everything here is something we run in production.
 Python
 PyTorch
 TensorFlow
- MLflow
- Weights & Biases
- ONNX
- NVIDIA
 Docker
 Kubernetes
 FastAPI
- AWS
 Grafana
 GitHub Actions
What this does for your business.
Models that reach users
Work that used to stop at a notebook becomes a dependable service the business can build on.
Quality you can see
Monitoring shows exactly how models perform in the real world, and alerts you before accuracy slips.
Faster iteration
Automated pipelines turn retraining and releasing a model from a project into a routine step.
From first call to shipped.
A planned, transparent arc with something you can see every week, so you always know exactly where the work stands.
Assessment
Week 1We review your models, data, infrastructure and current workflow, and agree the target setup.
Package and serve
Weeks 2 to 3The first model is containerised and deployed behind a production API with basic monitoring.
Automate the pipeline
Weeks 3 to 6Training, evaluation and registration become automated, reproducible pipeline steps.
Monitor and gate
Weeks 6 to 8Drift detection, quality gates and safe rollout strategies are added and tested.
Hand over and support
OngoingDocumentation, training for your team and optional ongoing platform support.
 AI & Data
A retail analytics team moves its demand-forecasting model from a notebook to a monitored service with automated weekly retraining, versioned releases and alerts when forecast accuracy starts to drift.
Talk to us about a project like thisQuestions we hear a lot.
Something else on your mind? Ask Luma in the corner, or reach the team directly.
Ask a questionYes. Most engagements start with models a team has already built. We productionise them without changing the science unless you ask us to.
Explore related services.
Need mlops & model deployment done right?
Tell us about your project, we'll come back with a concrete plan and timeline.